Best Janitor AI Models for Roleplay & Long Conversations

Three answers, depending on what you're after. JLLM+ for everyday spicy chat, DeepSeek V4 for cheap marathon sessions, and Claude-class models when you want writing that gets under your skin. Free JLLM still holds up if your budget is zero and your patience is high.
Here's the thing nobody tells you when you sign up. Janitor AI is not a model. It's a shop window, and the Janitor AI models sitting behind it are yours to swap. The bots are gorgeous, the character cards are filthy, and the actual brain doing the talking is something you pick yourself in API settings.
Pick wrong and your girl forgets your name by message 30. Pick right and she remembers the safe word you gave her three weeks ago.
So let's sort out which janitor models are worth your time in 2026, which janitor llm options survive a proper all-nighter, and how the new Permanent Memory setup stops your roleplay turning to mush.
✨ The Models At A Glance
| Model | Best For | Context Window | Rough Cost |
|---|---|---|---|
| JLLM+ (janitor+) | All-round long roleplay with zero setup | 5x free JLLM, around 40k to 45k | $12.99/month |
| JLLM Free | Broke, horny and patient | Around 8k to 9k | Free |
| JLLM-short | Fast sexting pace, snappy replies | Same as your JLLM tier | Free or $12.99 |
| DeepSeek V4 Pro | Serious roleplay on a modest budget | 1M tokens | $0.66 per 1M in, off-peak |
| Claude class | Prose, slow burn, emotional whiplash | Very large | Premium per token |
| Gemini class | Novel-length story arcs | Huge | Very cheap per token |
| GPT-5 class | Complex cards with strict rules | Large | Mid to premium |
| GLM 5.2 | Middle ground on price and quality | Large | About $1.25 per 1M in |
| Kimi K3 | Story arcs that run for months | 1M tokens | Pricey per message |
⚙ How This Actually Works On Janitor
Three routes. That's it.
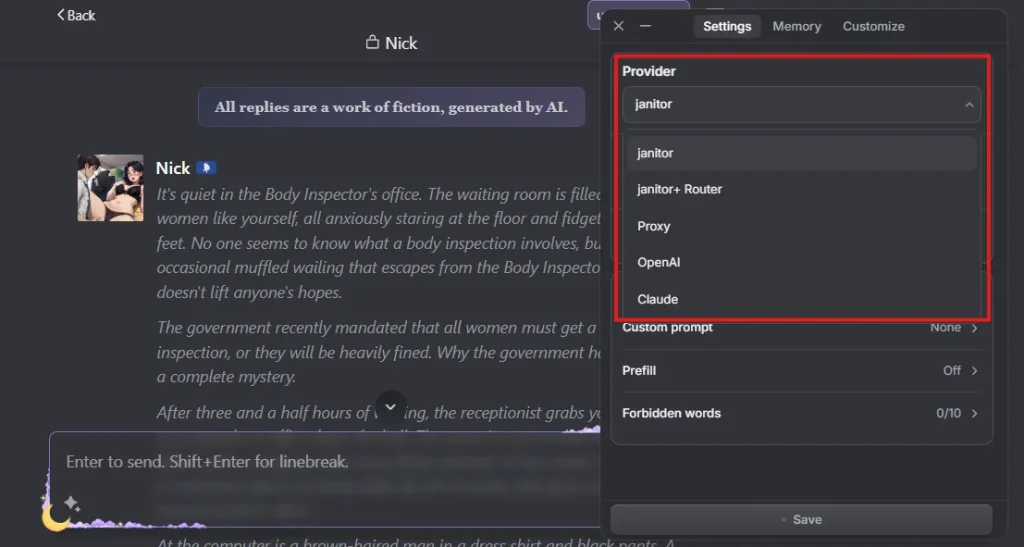
Router is web only at launch and locked to janitor+ subscribers. Mobile is promised later.
That's the whole map. Everything below is just picking which brain goes in the pretty head.
🚀 The Models, Ranked
1. JLLM+ (janitor+) – The Easy Answer for Most People
Janitor launched its first paid tier on 24 June 2026 at $12.99 a month, and the headline feature is the one that matters most for filthy long-form chat. Five times the context of free JLLM.
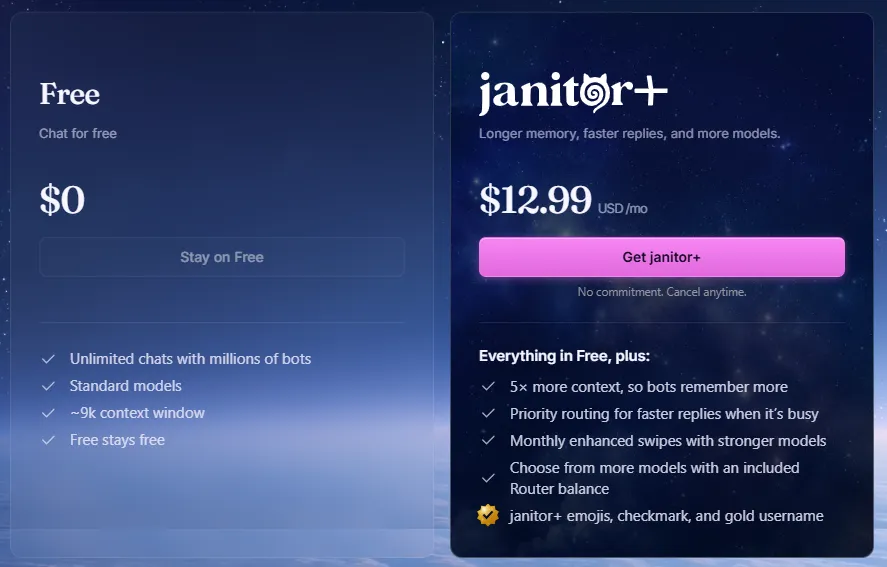
Free JLLM sits at roughly 8k to 9k tokens. Community testing puts janitor+ somewhere around 40k to 45k. In plain English, your girl stops developing amnesia halfway through the scene.
What you get on janitor+
It is still JLLM underneath, mind. The prose is serviceable rather than stunning, and the model can still slip into generic assistant mode when your card is badly written. You're paying for memory and speed, not a personality transplant.
If you only ever pick one thing off this list, pick this one. Zero setup, no API key, no proxy errors at 2am.
2. JLLM Free – Unfiltered, Costs Nothing, Forgets Everything
Still the model most people run, and still free with no card on file.
JLLM is unfiltered in a way that GPT and Gemini simply are not. Limitless tags mean limitless. Nobody is going to ban your account for what your bot said in the bedroom scene.
The catch is the ceiling. Around 25 to 30 messages in, your earliest exchanges start falling out of the window. She forgets how you met. She forgets the promise she made. And she starts speaking your lines back at you, which kills the mood faster than a phone call from your mum.
It also slows to a crawl at peak hours, and the replies run long and waffly in a way that can flatten the mood.
Perfect for a quick session. Painful for a story you actually care about.
3. DeepSeek V4 Pro – Best Value If You'll Paste One API Key
Still the community darling, though it costs more than it used to.
The headline number is the context window. 1 million tokens, which is more than a hundred times what free JLLM gives you. Your bot can hold an entire story arc without you touching a thing.
DeepSeek repriced on 16 August 2026, so ignore any guide still quoting the old flat rate. It now bills by the clock.
| DeepSeek V4 Pro, per 1M tokens | Off-peak | Peak |
|---|---|---|
| Input, cache miss | $0.66 | $1.32 |
| Input, cache hit | $0.022 | $0.044 |
| Output | $1.98 | $3.96 |
Peak is 01:00 to 04:00 and 06:00 to 10:00 UTC. Everything outside those two windows bills at half. Late-night sessions in the UK land off-peak, which is convenient given what most people use this for.
Prompt caching is the bit that keeps roleplay cheap. Your character card sits unchanged at the top of every request, so DeepSeek reuses it instead of reading it fresh. That drops repeated input to $0.022 per million, roughly 30 times cheaper than a cold read.
Worth knowing that V4 Flash runs the same 1M context at a third of the price, and independent scoring puts it one point behind Pro. For chat rather than heavy reasoning, Flash is the smarter buy.
Setup takes two minutes. Grab an API key from the DeepSeek platform or OpenRouter, open the triple bar menu in any chat, go to API settings, paste the key and the proxy URL, save.
It doesn't match Claude on sentence-level writing quality, and it can get a bit clinical during emotional beats. Great at plot, decent at feelings.
Best cost-to-filth ratio of any of the roleplay models on Janitor. Start here if you're leaving JLLM.
4. Claude Class – When the Writing Is the Whole Point
If you want the model that writes like a person rather than a bot doing an impression of one, this is it.
Claude-class models are the ones people single out for subtext, character psychology and prose that doesn't read like a fanfic written at 3am. Long context too, which suits arcs that build over weeks rather than minutes.
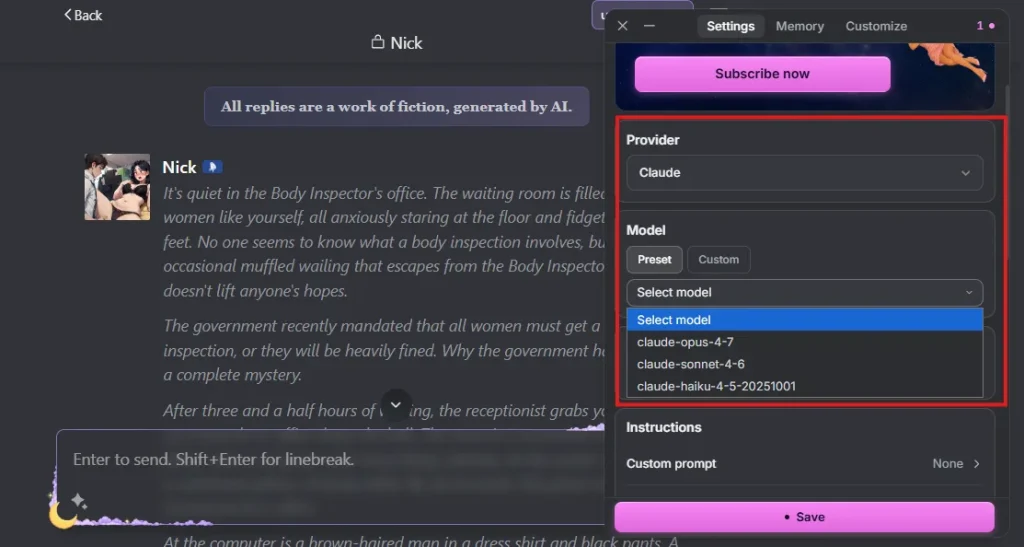
The trade-off is money and mood. It's premium per token, and the newer safety-tuned versions have annoyed a chunk of the roleplay crowd. Some scenes get pushback. Some don't. Test before you commit a big top-up.
Go here for slow-burn romance, jealousy arcs, morally messy characters, anything where the writing itself is the point.
Skip it if you mainly want quick, blunt, no-filter sexting. You'll be paying Michelin prices for a kebab.
5. Gemini Class – Huge Context, Tiny Bills, Slightly Prudish
Context is the whole pitch here.
Gemini's architecture holds absurd amounts of history, which is exactly what you want for a roleplay that has been running since spring. It's also stupidly cheap on the lighter tiers, with some Flash-class options around $0.075 to $0.20 per million tokens. You can chat for days on a $5 balance.
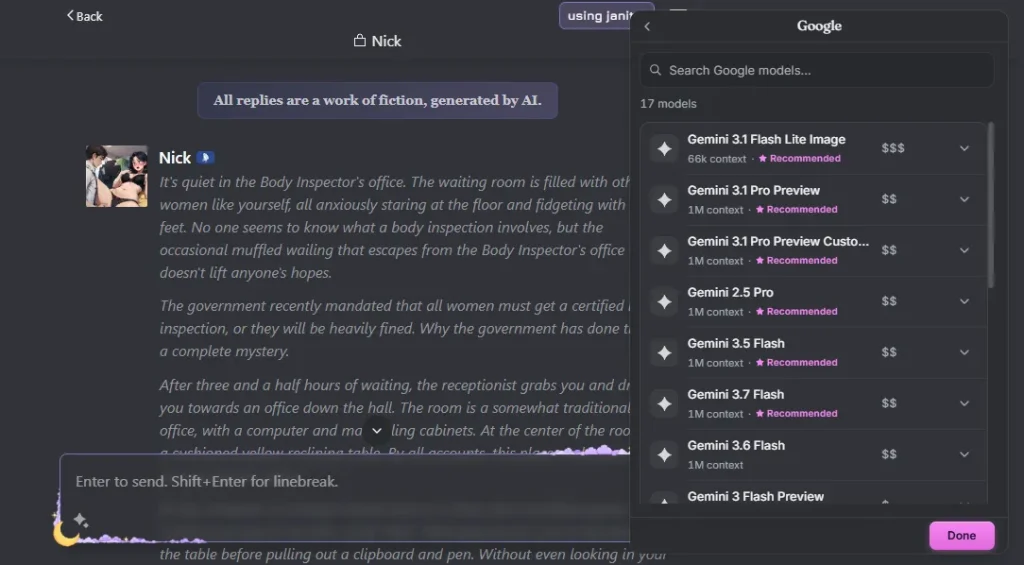
Why long chats love it
The annoying part is content policy. Gemini is not built for adult roleplay and it will get shy in places JLLM never would. Fine for romance and tension. Less fine for the hardcore end.
6. GPT-5 Class – For Cards With Fifty Rules
If your character card is a 3,000 token monster with rules about how she speaks, what she never says, and how she reacts when you mention her ex, GPT-class models follow instructions better than almost anything else.
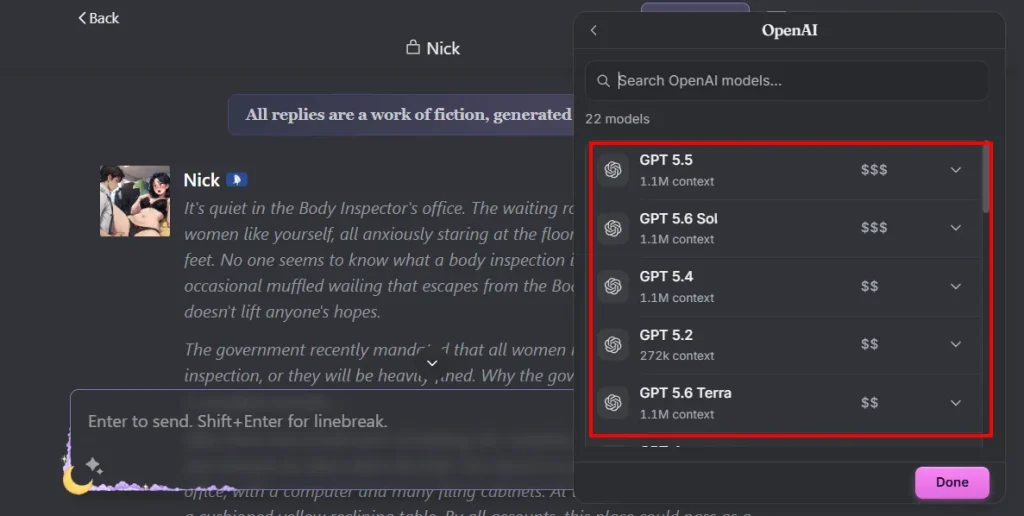
That's the selling point. Instruction-following. Formatting stays clean, asterisk actions stay consistent, and the bot stops speaking your lines for you.
The catch is the same as Gemini. Adult content is against usage policy on the official API, and people have lost access for it. Route it through a proxy that permits it, or accept a tamer scene.
7. GLM 5.2 – The Middle Option Nobody Mentions
GLM 5.2 has become one of the community's favourite backends alongside DeepSeek. Solid character consistency, decent creative range, sits neatly between budget and frontier.
Watch the maths though. GLM 5.2 shows about $1.25 per million input tokens, which reads as cheap. At 45k context on a cache miss, that's roughly $0.056 a message. Two hundred messages in a week and you're near $11 in credits.
Sticker price lies. Per-message cost tells the truth.
8. Kimi K3 – Best for Month-Long Story Arcs
A 2.8-trillion-parameter open-weight model built around long recall. DeepSeek matches it on raw context these days, so the pitch is no longer the number itself. It's how well Kimi actually uses the far end of that window.
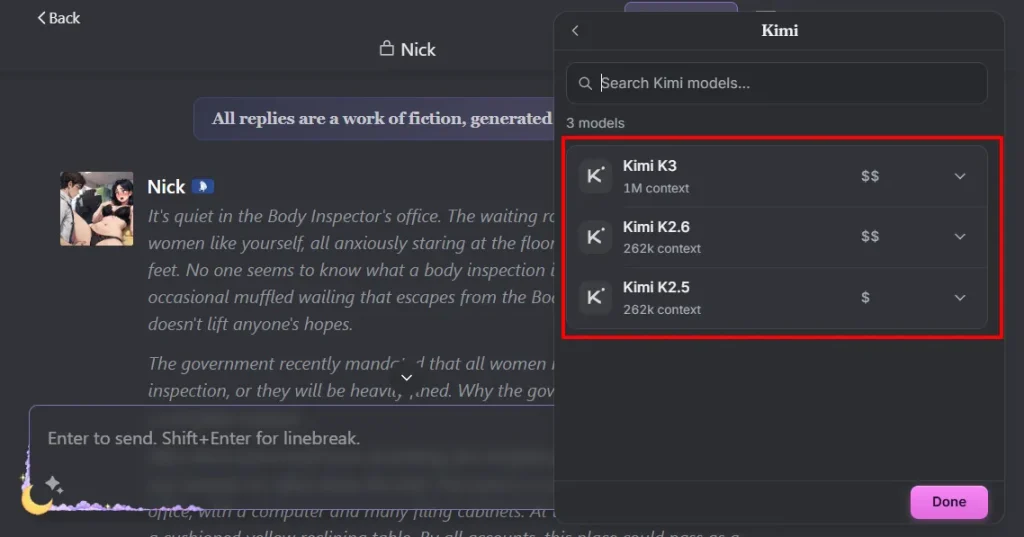
If your bot needs to recall a plot detail from a session you started in spring, this is the one that holds it most reliably.
Cost is the problem. One user reported paying $0.28 to $0.29 per message at 45k context. That $5 launch credit on Router? Gone inside an hour.
Beautiful for epics. Ruinous for daily use.
9. JLLM-Short – For People Who Hate Waffle
Janitor pushed its short response model to general access on 15 July 2026, and it fixed one of the oldest complaints on the platform.
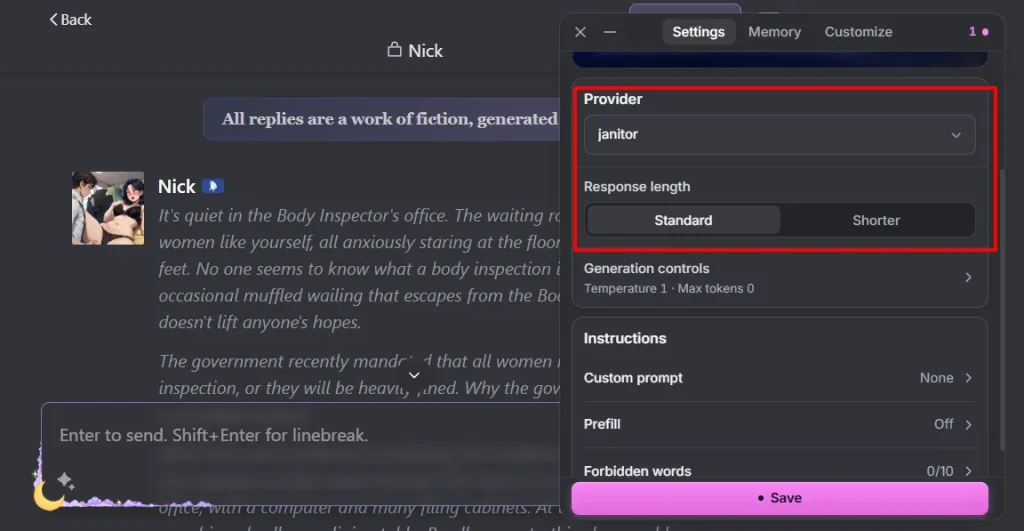
JLLM writes long. Sometimes gorgeously long. Sometimes four paragraphs of scenery when you asked her a yes or no question during a very specific moment.
JLLM-short cuts that. Snappier replies, faster back-and-forth, much better for sexting rhythm where momentum matters more than word count. Toggle it in model settings if your replies feel bloated.
🧠 Permanent Memory on Janitor AI, Explained Properly
This is the bit that actually decides how long your roleplay survives, and most people never touch it.
Janitor splits everything into two token types. Permanent tokens ride along on every single message you send. Temporary tokens are the live conversation, and they get pushed out as new messages come in.
| Token Type | What Lives There | Behaviour |
|---|---|---|
| Permanent | Chat Memory, Personality, Scenario, Advanced Prompts | Sent with every message, never drops out |
| Temporary | Your messages and the bot's replies | Oldest content falls off first |
Chat Memory is your permanent memory slot. Anything you write there gets structured as a permanent token and sits at the front of the context window on every turn. That's why your bot remembers a detail from message 4 even at message 200.
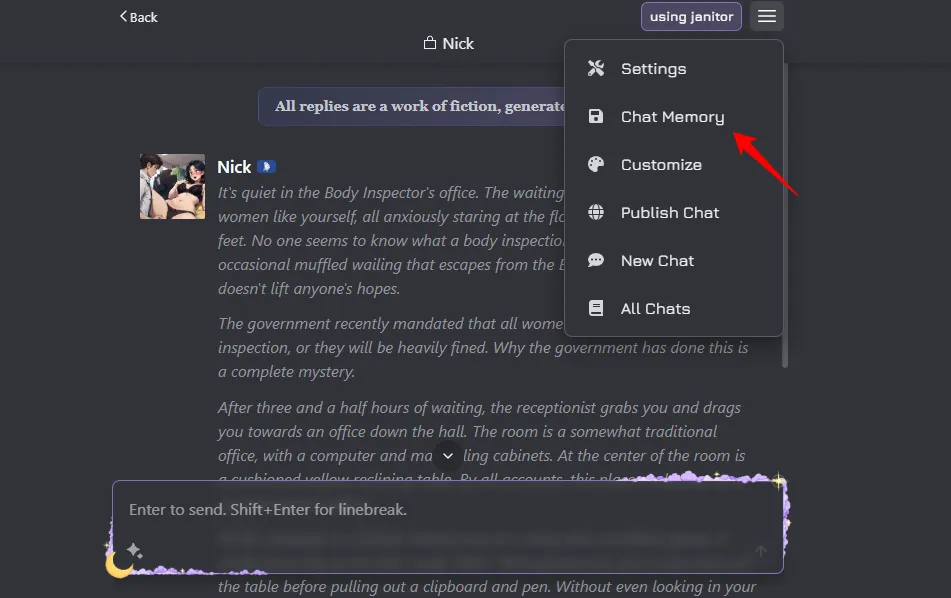
Janitor's own guidance is blunt about the ceiling. Bots perform best under 1,500 permanent tokens. Past 2,000 you're on thin ice, because every permanent token you add steals space from the actual conversation.
How to write Chat Memory that works
Lorebook is different. Use Chat Memory for facts that must always be visible. Use a Lorebook for world details that only matter when a specific keyword comes up. Repeating the same fact in both just burns your budget twice.
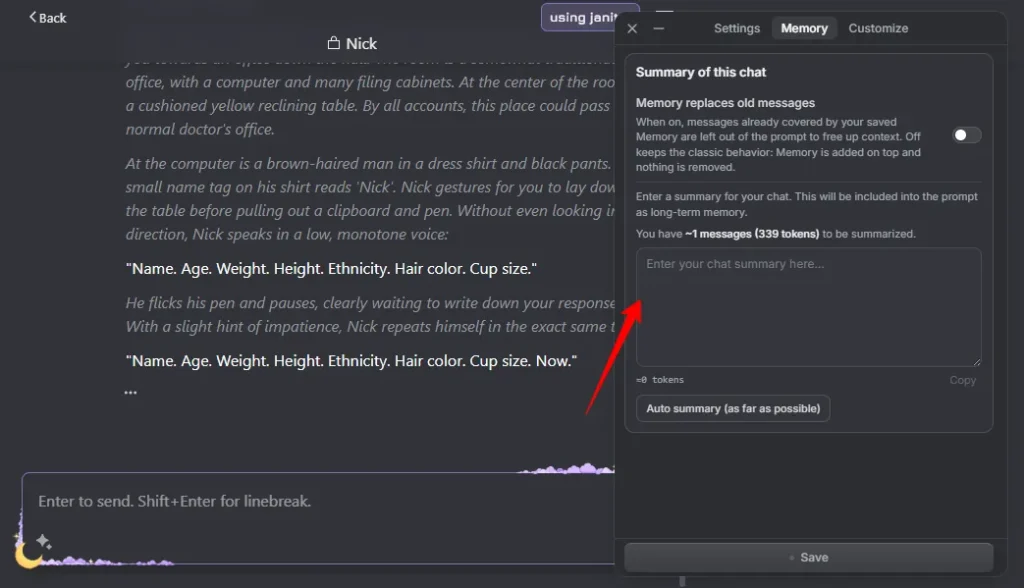
One heads-up. In mid-August 2026 Janitor accidentally shipped an experimental memory-replacement behaviour to everyone instead of a test group, and chats lost context. It was reverted.
There's now a clearly labelled toggle in the Chat Memory panel, off by default. If your bot went weirdly forgetful around then, that was why.
👀 Janitor+ Router, Worth It Or Not?
Router landed 30 July 2026 and gives janitor+ subscribers around 70 models from a dropdown. DeepSeek, Claude, GPT, Gemini, Grok and GLM all sit in there.
Each one shows its context window and per-token price before you chat, and you can sort by recommended, cheapest or largest context.
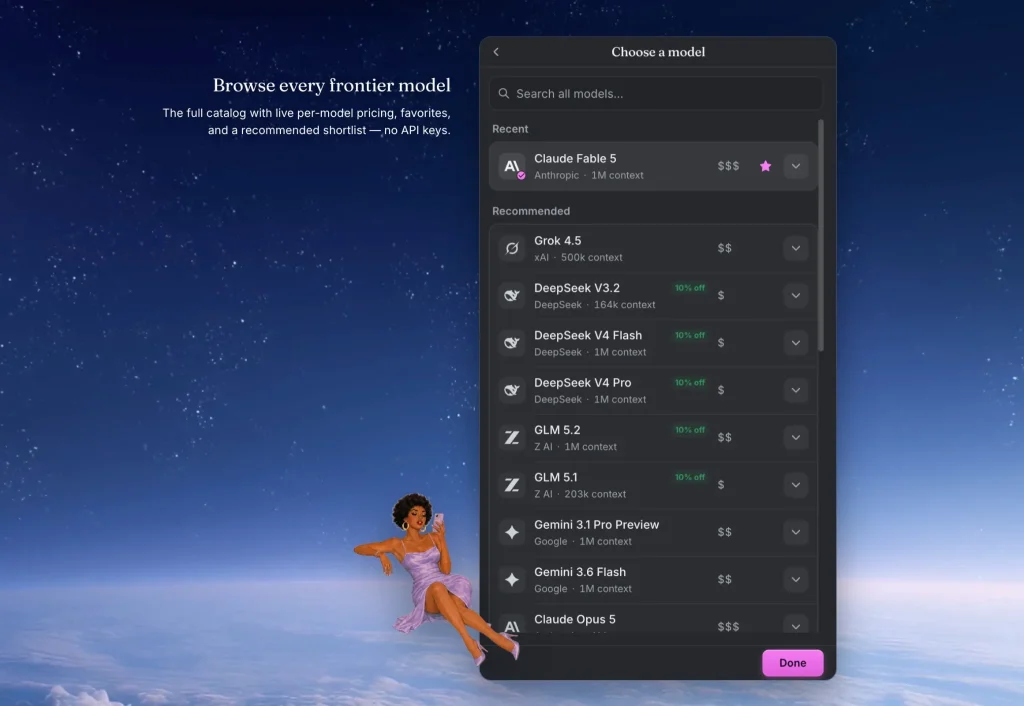
You also get settings the standard janitor api proxy route doesn't give you. Fifty forbidden words instead of ten, plus top-k, top-p, frequency penalty and reasoning effort controls.
The maths is less fun. Router stacks two charges. The $12.99 subscription, then metered credits on top. One subscriber worked it out at roughly $22.99 a month once you load $10 in credits, against paying the same token cost directly with no base fee.
There's a second charge people miss, because Janitor publishes no Router price list outside the app. The rates you see in the dropdown carry a markup over the provider's own.
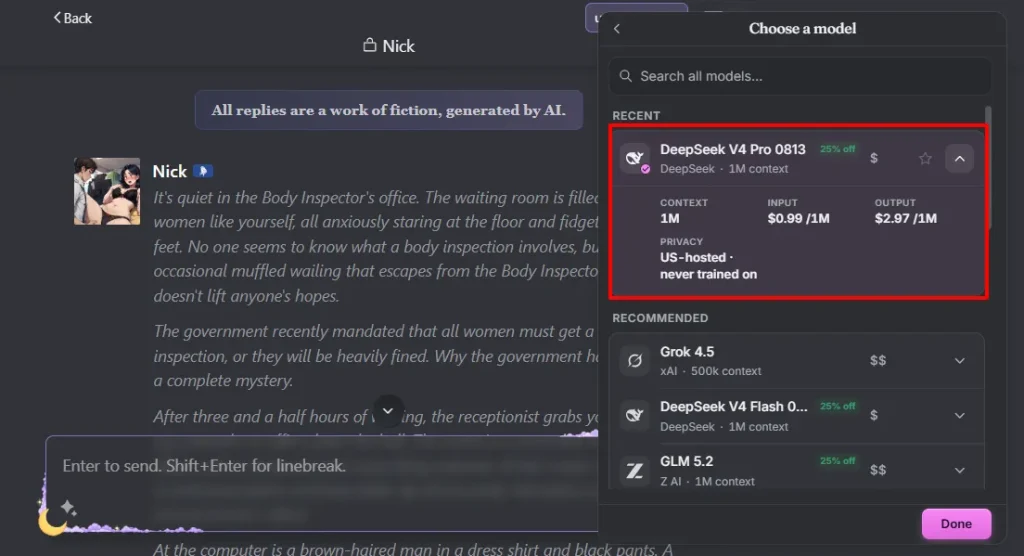
DeepSeek V4 Pro is listed on Router at $0.99 per million input and $2.97 per million output, against DeepSeek's own off-peak $0.66 and $1.98. That's a flat 50% on top, on every token, on top of the subscription.
| DeepSeek V4 Pro, per 1M | Direct, off-peak | Via Router |
|---|---|---|
| Input | $0.66 | $0.99 |
| Output | $1.98 | $2.97 |
Router does show you the context window, both token prices and a privacy note before you chat, which is more honesty than most proxy setups manage. It also runs US-hosted with no training on your chats, and for some people that alone is worth the premium over pointing at DeepSeek's own servers.
| Route | Monthly Base | Setup Effort |
|---|---|---|
| janitor+ Router | $12.99 required | None, pick from a dropdown |
| DeepSeek direct | $0 | API key plus proxy URL |
| OpenRouter | $0, 5.5% deposit fee | API key plus proxy URL |
Users reading the Router credit terms report that unspent balance locks behind an active subscription, so cancelling strands whatever you didn't spend. The terms page blocks outside requests, so check it inside your own account before loading a big balance.
If you already pay for janitor+ and proxies have genuinely defeated you, Router is a fair convenience buy. Subscribing purely to reach Router undoes the saving.
✅ Which One Should You Pick?
| You Want | Pick This |
|---|---|
| Zero setup, longer memory | JLLM+ |
| Free and unfiltered | JLLM Free |
| Cheapest long sessions | DeepSeek V4 Pro |
| Writing that hits emotionally | Claude class |
| A story running for months | Gemini or Kimi K3 |
| A card with 50 strict rules | GPT-5 class |
| Rapid-fire sexting pace | JLLM-short |
❌ Mistakes That Wreck Long Roleplays
📌 Questions People Actually Ask
Which Janitor AI model is best for long conversations?
JLLM+ is the easiest answer because it gives five times the context of free JLLM with no setup. For genuinely epic arcs, Gemini-class or Kimi K3 via proxy hold far more history, though you pay per token.
Is JLLM still free in 2026?
Yes. Janitor has confirmed the free tier stays. Unlimited chats, no API key, roughly 9k context. janitor+ at $12.99 a month is optional.
What is the cheapest good model for Janitor AI?
DeepSeek V4 Flash, which runs the same 1M context as Pro at a third of the cost. Prompt caching drops repeated character cards to a fraction of a cache miss, and chatting outside the two UTC peak windows halves every rate again.
Does Janitor AI have permanent memory?
Sort of, and it's manual. Chat Memory, Personality, Scenario and Advanced Prompts are treated as permanent tokens and get sent with every message. Keep the total under 1,500 tokens for best results.
Why does my bot forget things after 30 messages?
Free JLLM holds around 8k to 9k tokens. Once you pass it, your oldest messages get pushed out to make room. Move anything important into Chat Memory before it falls off.
Do I need an API key to use Janitor AI?
No. JLLM works out of the box. You only need a key if you want a third-party model through the janitor api proxy route, and even that is optional now Router exists for subscribers.
Can I still use my own proxy after Router launched?
Yes. Custom proxies and API keys work exactly as before. No removal has been announced. Talk of proxies being phased out is community speculation, not a stated plan.
Which model handles NSFW roleplay without complaining?
JLLM is the most permissive because it's built for it. DeepSeek through a proxy is the usual paid pick. GPT and Gemini both restrict adult content under their own usage policies.
Why are my replies suddenly really short?
You're probably on JLLM-short, which went to general access in July 2026. Toggle it off in model settings if you want longer replies back.
🎯 Final Word
There is no single winner among the Janitor AI models, and anyone claiming otherwise is selling something.
If you want it easy, pay the $12.99 and take JLLM+. Five times the memory, no proxy nonsense, done. If you want it cheap and you don't mind pasting an API key once, DeepSeek V4 Pro will run you a fiver a month and outlast almost everything else on this list. If you want writing that genuinely moves you, go Claude-class and accept the bill.
And honestly? Sort your Chat Memory out before you change model at all. Half the people complaining their bot has gone stupid are running a 4,000 token character card and an empty memory box.
Fix the memory, then pick the brain. Your girl will thank you for it.
Model pricing and context limits move constantly in this category. Everything here reflects what was published as of August 2026, so check the live figures before you top up.
Stay Updated with Us